Results
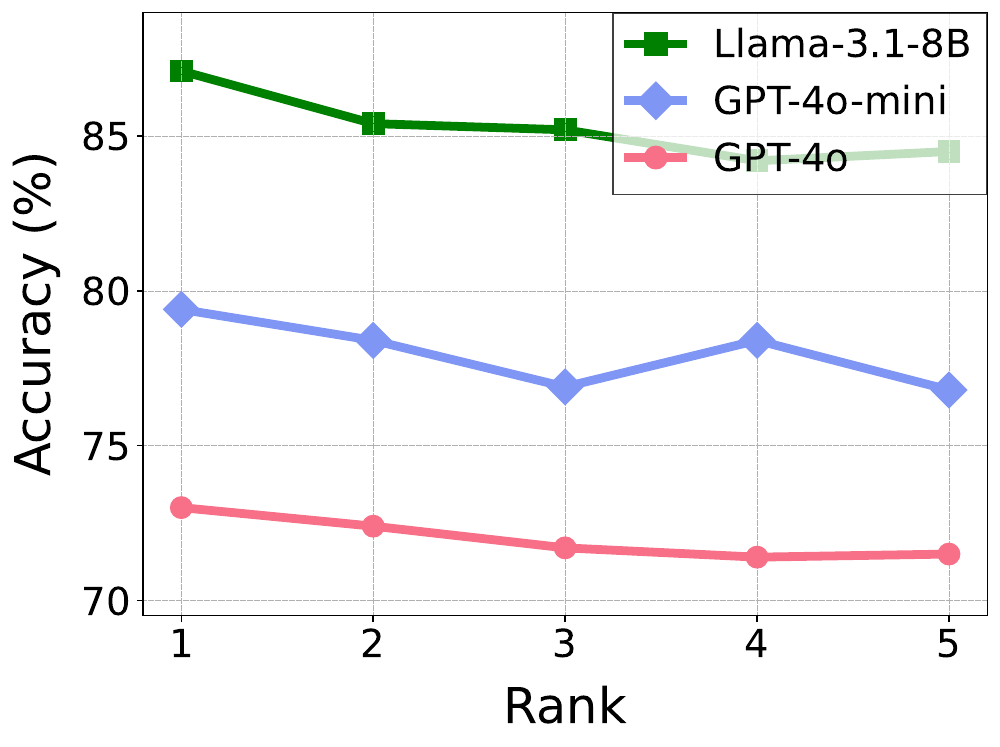
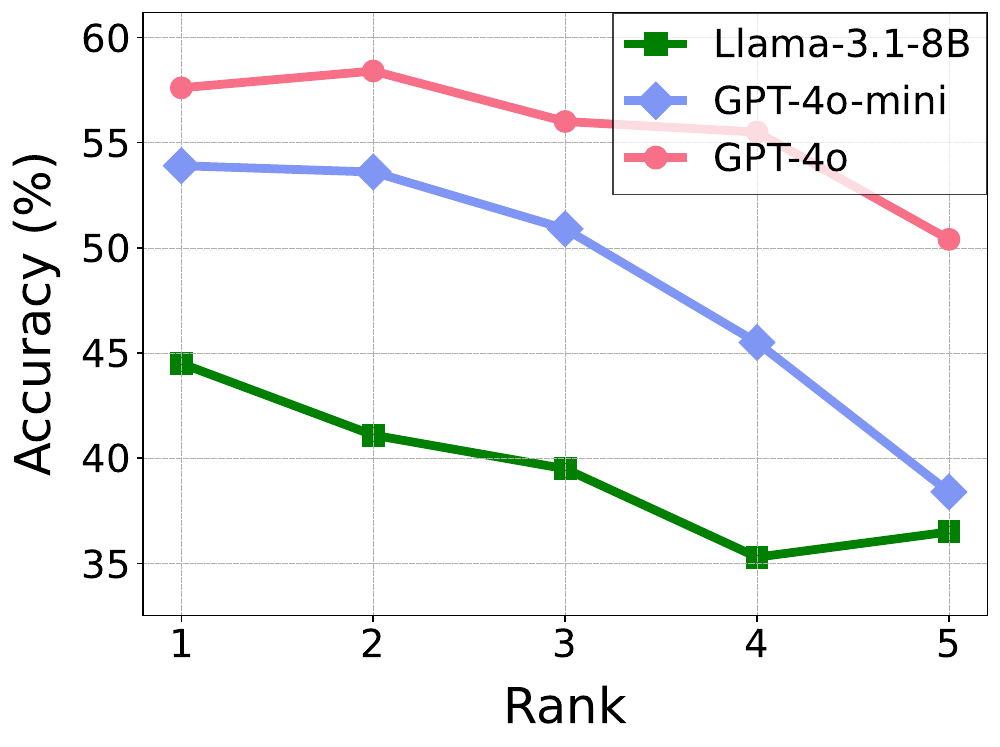
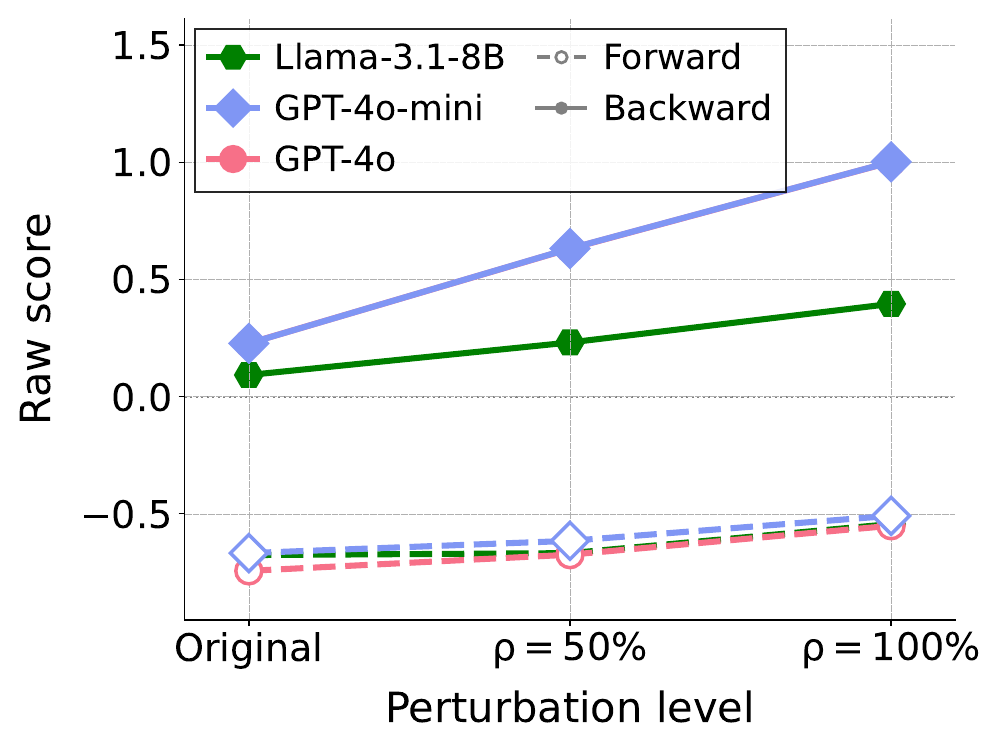
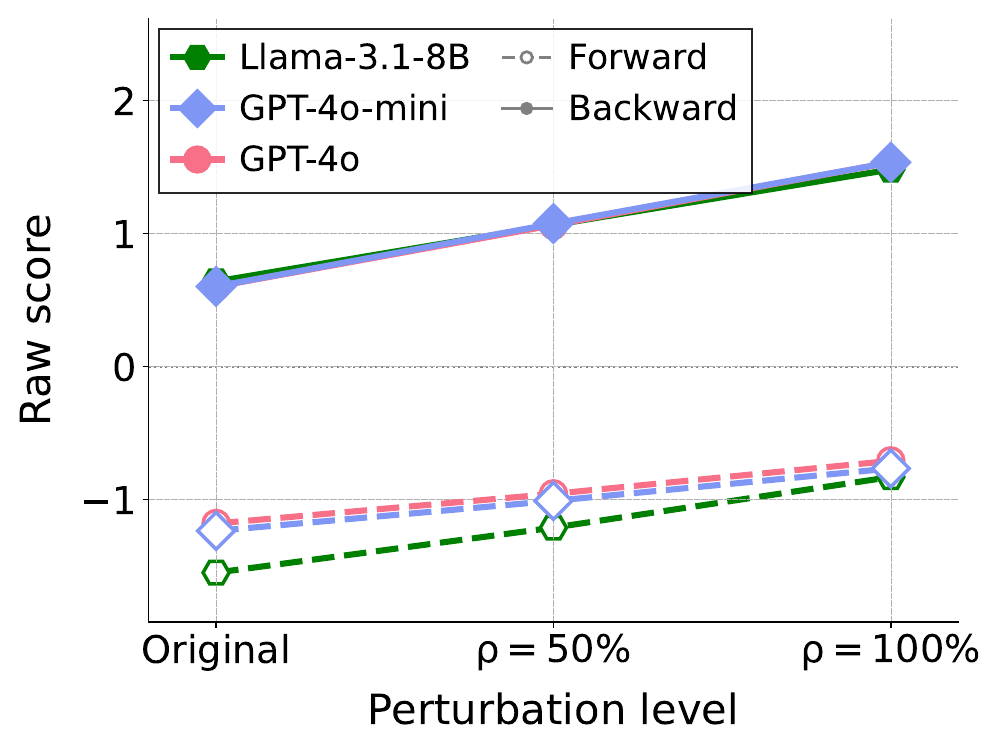
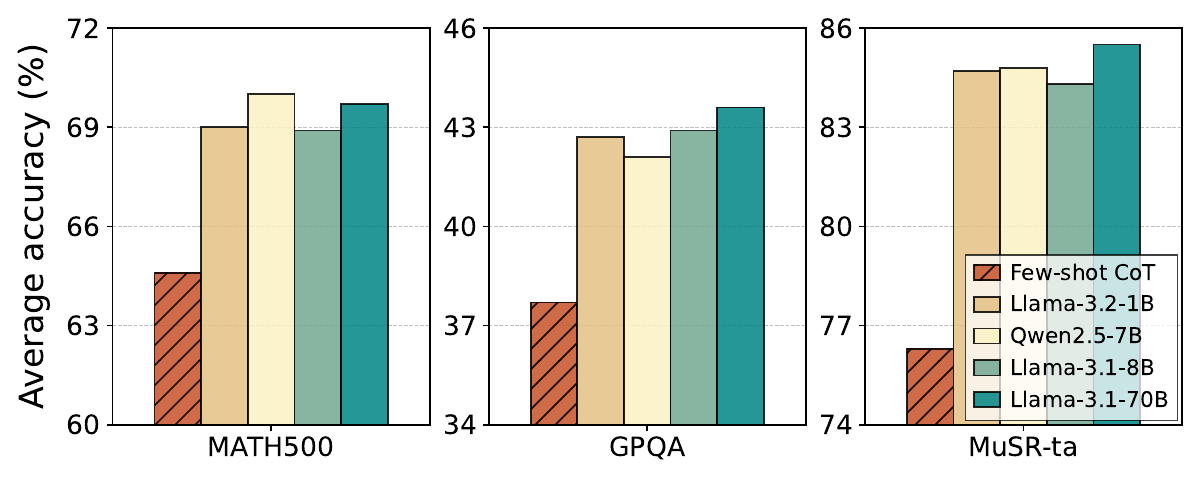
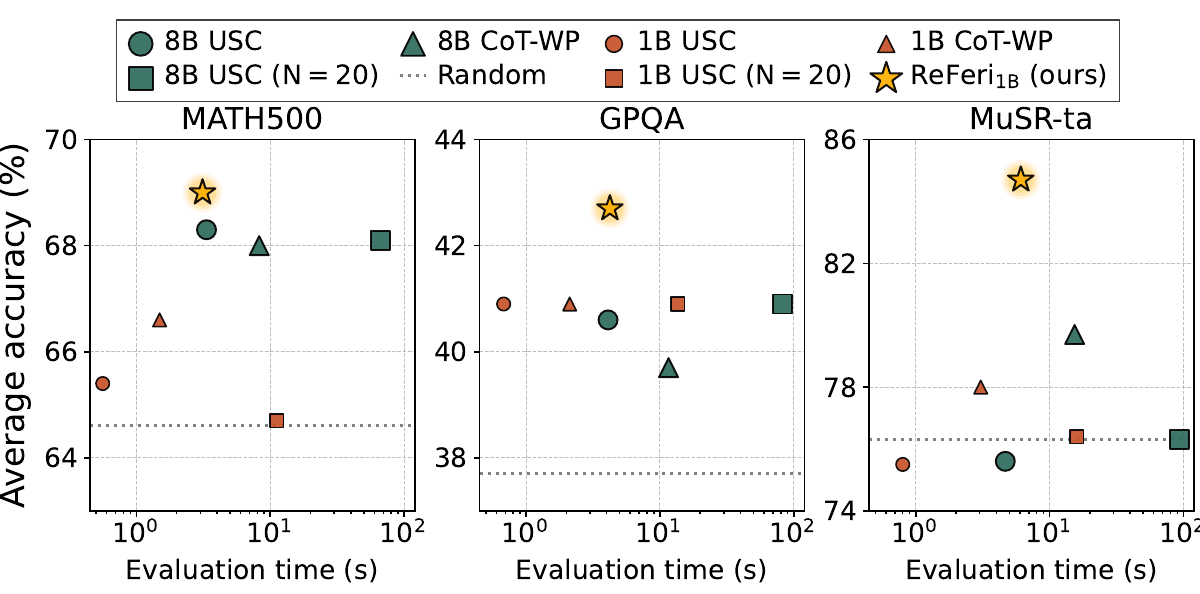
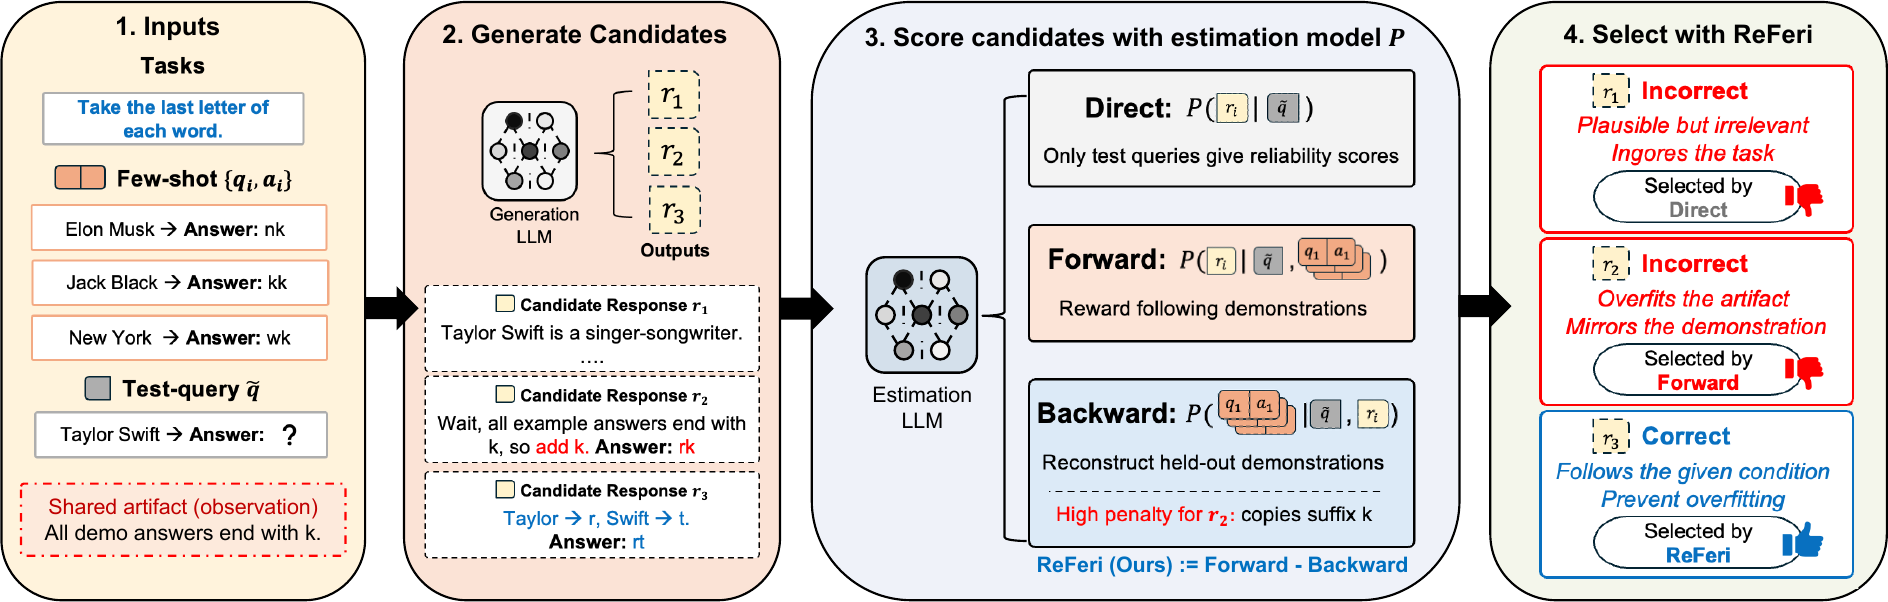
ReFeri consistently improves training-free response selection. Across three generation LLMs and seven reasoning benchmarks, ReFeri achieves an 8.2% average relative gain over random selection and a 2.6% average relative improvement over the strongest prior training-free baseline.
| Methods | MuSR-taAcc. | MuSR-opAcc. | GPQAAcc. | MATH500Acc. | DROPEM / F1 | HotpotQAEM / F1 | MMLU-PROAcc. | Avg. |
|---|---|---|---|---|---|---|---|---|
| GPT-4o | ||||||||
| Zero-shot CoT | 67.5 ±0.8 | 62.1 ±0.4 | 49.5 ±0.8 | 77.1 ±0.6 | 74.2 ±0.8 / 84.9 ±0.4 | 37.8 ±0.3 / 50.3 ±0.4 | 74.0 ±0.2 | 63.2 ±0.2 |
| Few-shot CoT | 87.2 ±0.6 | 69.6 ±0.6 | 47.3 ±1.7 | 75.5 ±0.1 | 80.4 ±0.2 / 89.0 ±0.2 | 44.9 ±0.4 / 58.6 ±0.3 | 73.7 ±0.2 | 68.4 ±0.3 |
| LEAP | 88.1 ±1.6 | 68.0 ±1.2 | 47.8 ±2.8 | 75.2 ±0.4 | 81.0 ±0.5 / 89.4 ±0.4 | 44.5 ±0.6 / 57.8 ±0.5 | 73.9 ±0.2 | 68.4 ±0.4 |
| USC | 85.9 ±1.9 | 71.5 ±0.7 | 48.2 ±1.6 | 77.3 ±0.3 | 81.8 ±0.3 / 90.2 ±0.1 | 45.9 ±0.3 / 60.2 ±0.5 | 74.9 ±0.5 | 69.4 ±0.5 |
| CoT-WP | 88.3 ±0.2 | 67.5 ±1.4 | 49.5 ±1.8 | 78.1 ±0.6 | 83.3 ±0.1 / 90.5 ±0.8 | 46.3 ±0.9 / 59.6 ±0.9 | 74.4 ±0.3 | 69.6 ±0.0 |
| Self-Certainty | 88.9 ±0.5 | 71.1 ±2.1 | 50.2 ±0.8 | 77.7 ±0.4 | 81.1 ±0.8 / 89.4 ±0.3 | 43.9 ±0.4 / 57.7 ±0.1 | 74.6 ±0.4 | 69.6 ±0.4 |
| ReFeri | 90.8 ±0.4 | 73.7 ±2.2 | 51.8 ±0.3 | 78.5 ±0.6 | 83.6 ±0.2 / 90.9 ±0.6 | 46.9 ±0.4 / 61.0 ±0.7 | 75.4 ±0.3 | 71.5 ±0.4 |
| ReFeri1B | 90.7 ±0.2 | 74.1 ±3.8 | 51.0 ±1.3 | 78.3 ±0.6 | 83.3 ±0.5 / 90.7 ±0.1 | 46.5 ±0.8 / 60.5 ±0.2 | 75.1 ±0.1 | 71.3 ±0.4 |
| GPT-4o-mini | ||||||||
| Zero-shot CoT | 57.6 ±1.3 | 58.9 ±2.7 | 41.8 ±1.0 | 75.8 ±0.6 | 77.2 ±0.7 / 85.1 ±0.8 | 31.5 ±0.4 / 41.6 ±0.4 | 63.0 ±0.1 | 58.0 ±0.1 |
| Few-shot CoT | 77.5 ±0.5 | 60.3 ±0.8 | 42.4 ±1.1 | 74.7 ±0.7 | 76.5 ±0.2 / 82.9 ±0.2 | 33.6 ±0.3 / 44.9 ±0.2 | 63.0 ±0.2 | 61.1 ±0.2 |
| LEAP | 74.9 ±3.2 | 60.3 ±3.2 | 43.6 ±0.3 | 74.5 ±0.1 | 75.4 ±0.4 / 82.5 ±0.5 | 33.3 ±0.6 / 44.5 ±0.5 | 63.1 ±0.2 | 60.7 ±0.1 |
| USC | 76.5 ±2.5 | 60.5 ±1.0 | 44.6 ±1.2 | 76.4 ±1.2 | 78.8 ±1.7 / 85.0 ±1.0 | 35.1 ±0.2 / 47.0 ±0.3 | 64.2 ±0.5 | 62.3 ±0.5 |
| CoT-WP | 79.3 ±1.3 | 58.5 ±2.6 | 41.9 ±0.9 | 77.0 ±0.7 | 76.9 ±0.6 / 82.7 ±0.6 | 34.7 ±0.9 / 45.9 ±0.9 | 64.6 ±0.4 | 61.8 ±0.5 |
| Self-Certainty | 81.7 ±1.6 | 60.1 ±0.6 | 41.6 ±2.8 | 76.8 ±1.0 | 76.7 ±0.4 / 83.1 ±0.6 | 34.7 ±0.1 / 45.9 ±0.4 | 63.9 ±0.8 | 62.2 ±0.1 |
| ReFeri | 83.1 ±0.2 | 62.0 ±0.6 | 44.6 ±2.6 | 78.2 ±0.4 | 79.1 ±0.5 / 84.7 ±0.8 | 35.7 ±0.4 / 47.4 ±0.6 | 64.9 ±0.4 | 63.9 ±0.5 |
| ReFeri1B | 82.8 ±0.4 | 62.9 ±1.4 | 45.3 ±1.2 | 77.7 ±0.2 | 78.3 ±0.8 / 83.9 ±1.0 | 35.1 ±0.5 / 46.6 ±0.5 | 64.6 ±0.5 | 63.8 ±0.2 |
| LLaMA-3.1-8B | ||||||||
| Zero-shot CoT | 43.3 ±1.5 | 51.9 ±1.2 | 20.9 ±0.7 | 42.9 ±1.3 | 59.7 ±0.7 / 65.9 ±0.5 | 15.7 ±0.6 / 21.7 ±0.5 | 40.1 ±0.4 | 39.2 ±0.2 |
| Few-shot CoT | 64.5 ±2.2 | 53.4 ±0.8 | 23.7 ±0.3 | 42.4 ±0.5 | 61.1 ±0.7 / 66.5 ±0.9 | 19.3 ±0.3 / 25.4 ±0.4 | 39.2 ±0.4 | 43.4 ±0.5 |
| LEAP | 64.7 ±3.9 | 53.3 ±5.1 | 26.8 ±1.8 | 41.9 ±0.5 | 57.0 ±1.1 / 62.6 ±1.3 | 19.9 ±0.2 / 26.7 ±0.1 | 36.5 ±0.7 | 42.9 ±1.2 |
| USC | 67.7 ±4.5 | 54.8 ±2.2 | 28.1 ±3.1 | 48.5 ±1.2 | 68.6 ±0.9 / 74.3 ±1.3 | 25.5 ±1.1 / 33.4 ±1.0 | 45.8 ±0.4 | 48.4 ±1.1 |
| CoT-WP | 71.9 ±0.6 | 53.1 ±1.4 | 30.5 ±2.5 | 48.1 ±1.7 | 71.0 ±0.5 / 75.1 ±0.6 | 25.7 ±0.1 / 33.2 ±0.4 | 45.4 ±0.7 | 49.4 ±0.4 |
| Self-Certainty | 72.4 ±3.6 | 55.9 ±0.6 | 30.8 ±2.6 | 50.7 ±2.2 | 70.8 ±1.1 / 76.2 ±1.0 | 25.2 ±0.5 / 32.9 ±1.0 | 44.5 ±0.8 | 50.0 ±1.1 |
| ReFeri | 76.5 ±3.4 | 57.5 ±0.5 | 33.5 ±1.7 | 50.2 ±1.6 | 70.9 ±1.6 / 76.3 ±0.5 | 25.7 ±0.7 / 33.6 ±0.6 | 44.7 ±0.5 | 51.3 ±0.6 |
| ReFeri1B | 76.9 ±3.2 | 55.5 ±0.8 | 31.8 ±2.0 | 50.1 ±1.7 | 70.9 ±1.4 / 75.8 ±1.0 | 25.3 ±0.5 / 32.9 ±0.6 | 44.2 ±0.5 | 50.7 ±0.5 |
ReFeri uses a LLaMA-3.1-8B estimator; ReFeri1B uses LLaMA-3.2-1B. Bold: best, underlined: second-best within each generation model.
ReFeri scales with the candidate pool. As the number of responses increases from 1 to 20, accuracy improves from 75.8 to 79.4 on MATH500, 41.4 to 45.5 on GPQA, and 75.6 to 86.0 on MuSR-ta, while several competing training-free selectors saturate or degrade.
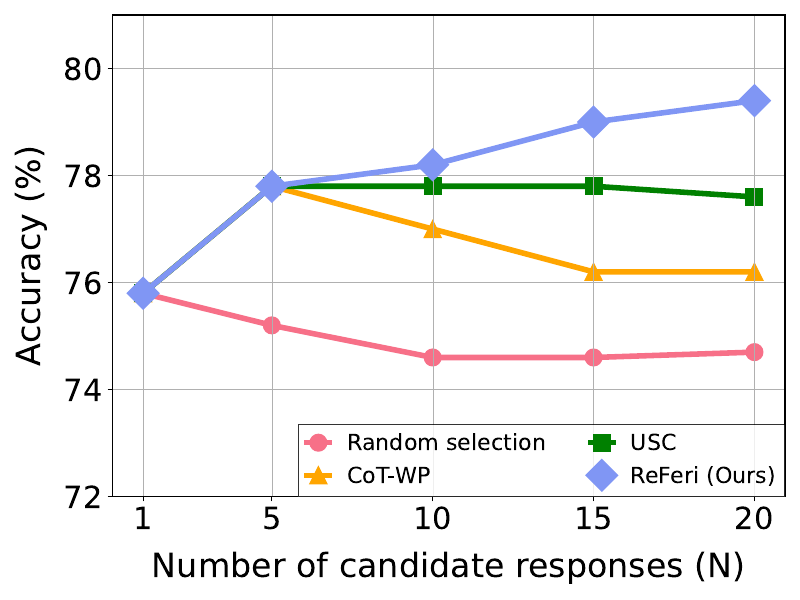
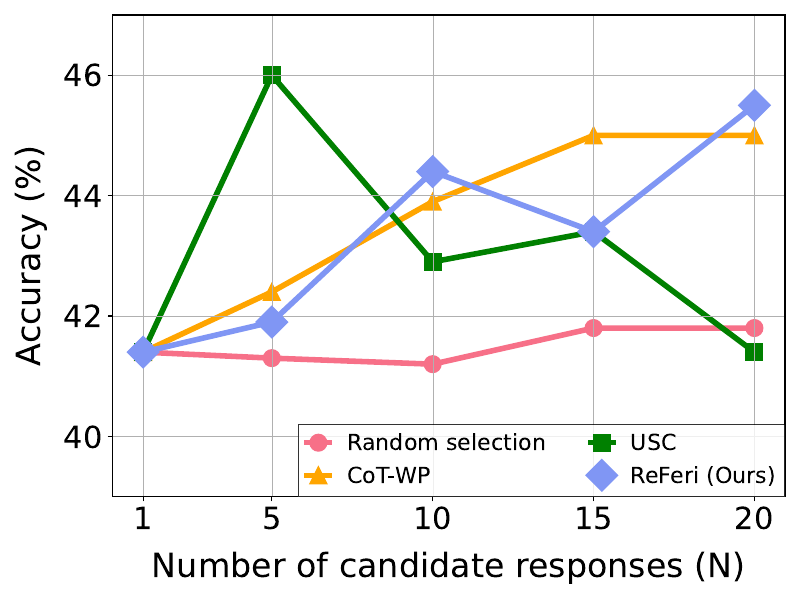
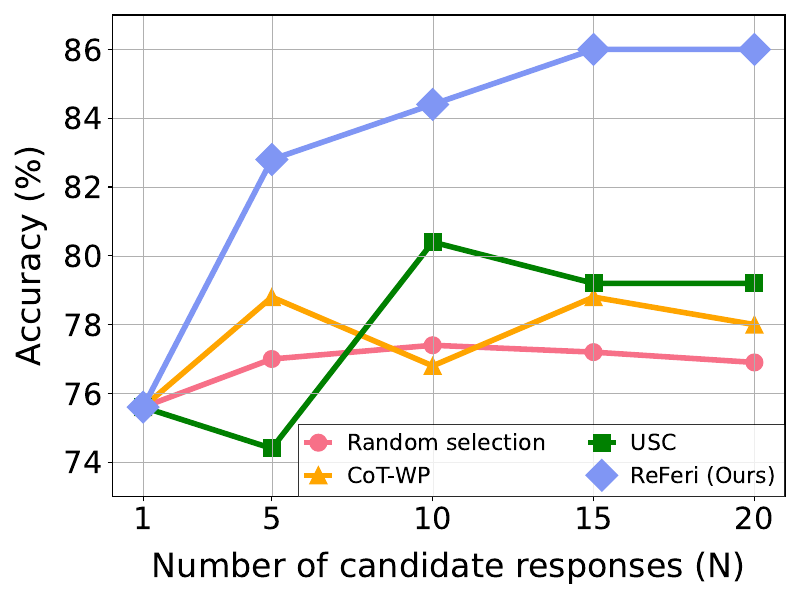
GPT-4o-mini generates N = 1–20 candidates with Few-shot CoT; each method selects one.